Post Abstracts
Seventeenth in the Array Languages series, a companion to the sixteenth: my opinions, from experience, about what makes a programming language practical, read back out of X_eTaL's decisions. Read code at the point of use; one meaning per thing and no guessing; errors before the program runs; functional by default and practical where it must be; borrow on purpose and do not copy; keep the core small and grow it only on evidence; and treat the tools as part of the language. Macros and extensions keep the core concise, and the price of that is guarding the macros well.
A threshold and a ReLU activation function, written once in X_eTaL and once in Mojo, run on the Adreno 702 GPU in an Arduino UNO Q, a GPU Mojo does not target. X_eTaL gets there through its own OpenCL backend; Mojo gets there first as the host program, then with its own kernel, retargeted from NVIDIA's IR to SPIR-V. Both reach the same Freedreno instructions. The same Mojo kernel also runs on Apple and NVIDIA GPUs, and X_eTaL's Mojo backend now runs eleven demos. What one day of work established, and what it did not.
Sixteenth in the Array Languages series: how X_eTaL became the language it is, decision by decision. APL's arrays and right-to-left reading, typed in ASCII and drawn as notation; Haskell's types but not its evaluation; Rust's macros, lints and error messages; tuples for state that arrays packed badly. Most changes came the way a page fault is resolved: a library, a macro library or an extension tried to do something, failed or found it clumsy, and the language answered with a feature, a choice among alternatives, or a refusal. Here are the choices in order, the few that deserve a story, and the features left out because they would have cluttered the language.
Fifteenth in the Array Languages series: a parsing library for people who write X_eTaL macros. Every macro that reads an embedded notation, an equation, a pipeline, a stencil, has had to write its own reader, and a hand-written reader that uses part of its text and drops the rest gives silent wrong answers. A shared library whose parses must reach the end of their input, with errors that point at the place in the text, makes that whole class of bug a compile-time error.
One small ML array program, a threshold and two ReLUs written in X_eTaL, followed all the way down: X_eTaL source to its Core, to an accelerator IR, to Mojo, to the PTX NVIDIA's driver finishes into machine code, to Apple's AIR and AMD's GPU code from the same Mojo file, and on to the other roads, CUDA C++ through nvcc and OpenCL C compiled by the driver at run time. What each toolchain needs installed, what it hands to the next, and where Mojo uses CUDA and where it goes around it.
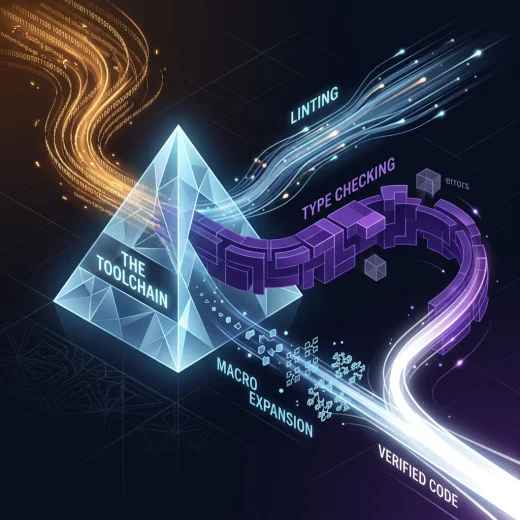
Fourteenth in the Array Languages series: how X_eTaL tries to turn mistakes into errors as early as possible. A type error before the program runs is good, a run-time error is worse, and a silent wrong answer is the worst, and writing the equations post turned up three of those in a day-old macro library. This post follows the ladder rung by rung, cheapest to fix first, from the editor through macro expansion, types, lints and tests to run time, with a real example of each, and ends with what changed so that class of mistake is caught.
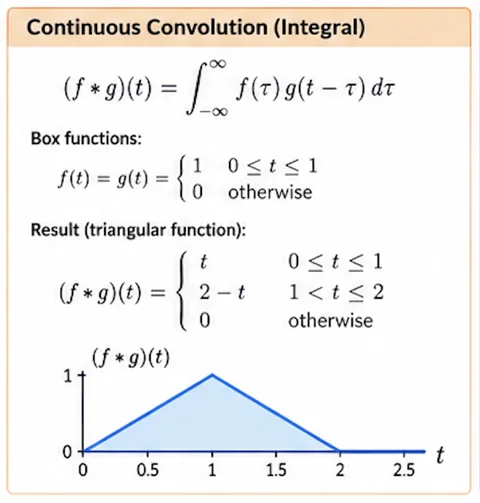
Thirteenth in the Array Languages series: after sums and pipelines, integrals. A continuous convolution is an integral, and a computer can only approximate one, so the plan keeps the mathematics and the numerical method apart: an integral written as the paper prints it, typeset exactly, and computed by a stated rule on a stated grid, with improper integrals refused rather than quietly cut short. The first deliverable is a short Blender video, drawn from X_eTaL's own numbers, comparing convolution, correlation and the integral of two box functions.
LeetCode 1979 asks for the greatest common divisor of an array's smallest and largest numbers. Conor Hoekstra solved it in sixteen languages; here it is in five, APL, J, Haskell, Lisp and X_eTaL, all asking for the same shape: one argument handed to two functions, their results to a third. APL and J write that fork as three functions side by side; X_eTaL needs brackets around them. This post is about why. Along the way the fork becomes a bird: Curry's Phoenix, just added to X_eTaL's Combinators library.
Array Languages #12: ML Pipelines as X_eTaL Macros
Oct 18, 2026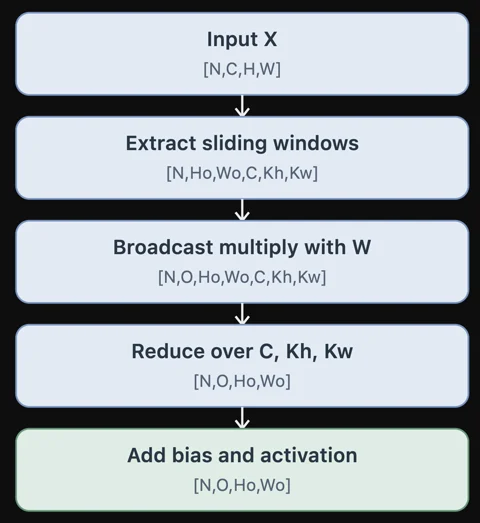
Twelfth in the Array Languages series: a macro that writes an ML model's data flow left to right, data first and then each layer in turn, in a language that reads right to left. Stages can be named for later use and given shapes that are checked, a pipeline can be written one stage per line, and the whole thing expands to ordinary X_eTaL that xetal expand shows. It is a library, Flow, in X_eTaL-ML, checked against hand-written code and against random pipelines.
Saw #15: agentrail, Correcting the Record
Oct 18, 2026
agentrail keeps AI coding agents on a numbered plan, a saga, committed with the code. With several agents now working one family of repositories at once, work started happening where the saga's cursor never goes: in another repository, in a parallel lane, after the plan changed. The existing commands could not record that without corrupting a neighbor's history. So I asked Claude to fix the tool: three new commands, close, edit and reserve, a cursor that never lands on finished work, and a report of stranded steps with the command to fix each.
Array Languages #11: Math Equations as X_eTaL Macros
Oct 17, 2026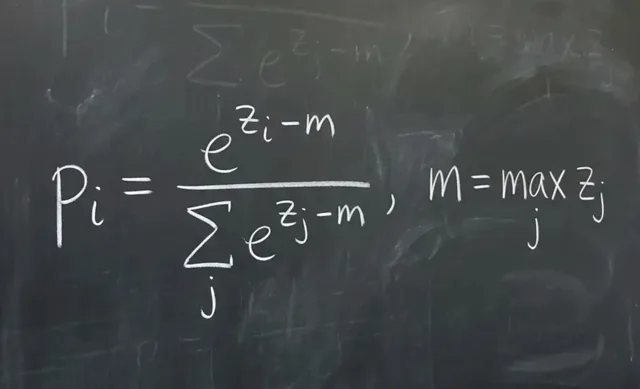
Eleventh in the Array Languages series: macros that take an equation as an ML paper prints it, a CNN's triple sum for one, and give back the array computation, its LaTeX, or both. They are a new library, Equations, in X_eTaL-libraries, with no change to the language: the point is to find out how far macros can carry ML notation before any new syntax is justified.
Tenth in the Array Languages series: X_eTaL programs on GPUs through a second backend, Mojo. Post #7's GPU work lowers X_eTaL source to an accelerator IR and runs it through OpenCL, which Apple deprecated in 2018. Now the same IR also goes to a Mojo emitter: X_eTaL source in, Mojo out, built into a library with a C interface, and run through Metal on an Apple M1 Max and through NVIDIA's driver on an RTX 5060 Ti, with nothing written or lowered by hand. Five demos give the X_eTaL evaluator's answers on both. Matrix products, gathers and the ML models come next; the older cards stay with OpenCL unless Mojo can be configured for them.
Ninth in the Array Languages series: X_eTaL drives Blender. An X_eTaL program works out a scene as arrays, every object's place, size and color, every key it moves to, the camera's path and the captions, and a small library writes those arrays into Python as numbers for a fixed player script that Blender runs. Literate documents in progress show the whole path, X_eTaL to Python to a Blender render. Then Blender draws the rest of the series: arrays becoming a model, the HEX1000 machine's memory, a kernel on two GPUs, a tiny network stage by stage, and a matrix product and a softmax, animated.
Eighth in the Array Languages series: X_eTaL-fpga turns X_eTaL programs into circuits, written out as Verilog. An add on eight numbers becomes eight adders, a sum becomes a tree of adders or one adder used over eight clocks, and a step function over a state vector becomes registers. Every circuit is checked against the evaluator's answer, bit for bit, through layers of simulation and the standard Verilog tools. And now on real hardware: HEX1000, a 4-bit calculator machine in the spirit of the TMS1000, specified in X_eTaL, runs on a Tang Nano 9K and calculates over its USB serial port, built with open tools on a Mac and an Arch Linux machine.
Seventh in the Array Languages series: X_eTaL-gpu takes X_eTaL programs to GPUs through OpenCL, old and new. A function written in ordinary X_eTaL is now marked for the GPU with a macro, ᵍᵖa̲ccel<, and runs there, lowered from its own source. Measured so far on an M1 Max and an RTX 5060 Ti, large, product-heavy work in big batches runs 25 to 220 times faster than X_eTaL's own evaluator. Against tuned CPU code a small model does not win yet, and the next examples are built to the rule the measurements give: upload little, keep the data on the GPU, and do a lot of arithmetic per byte.
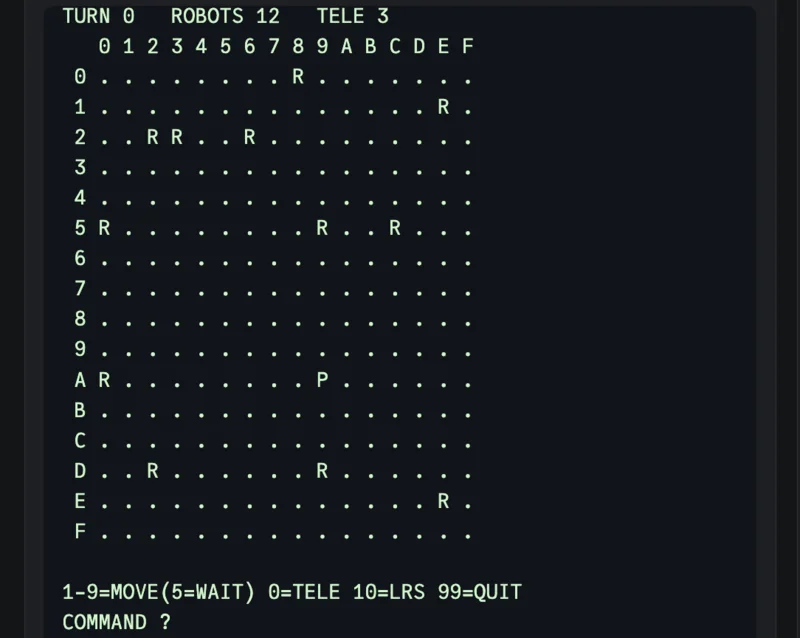
Sixth in the Array Languages series: X_eTaL-games, where every game illustrates an array-language idea and happens to be playable. Twenty are live in the browser, from the horse race this blog began with to asteroids and a tower defense in 3D, and each one maps to a concept: a vector moved by one expression, an outer product of comparisons, rotation and reduction, compress, a fixed point, a product mod 2, an entity-component system as one matrix. The games are also how the language gets dogfooded: they hold state, take input and keep time, and what they cannot do yet goes back to the language as an ask.
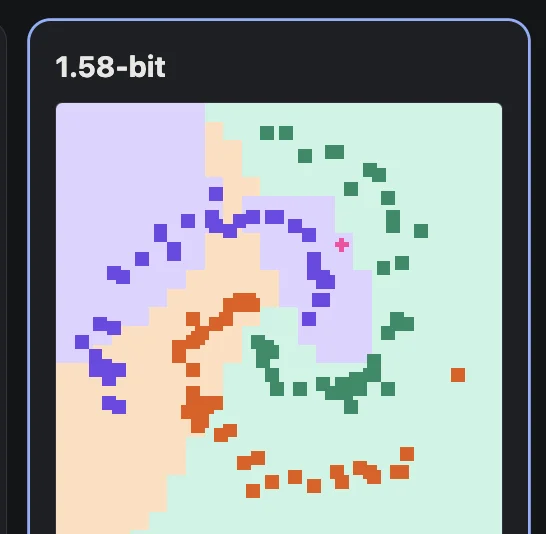
Fifth in the Array Languages series: the machine learning the whole project exists for. X_eTaL-ML now has ten live demos, and three of them train in X_eTaL itself, a small CNN among them, in the browser. Its six libraries range from a neural-network vocabulary, quantization, convolution and word embeddings to classic machine learning and a macro library that writes a network and its training step from one line. Here is what runs, what the code looks like, what comes next, and how X_eTaL, sw-MLPL and Rosetta M fit together on the way to a later language.
A short one. This week's sharpening was guards and benches: the blog now refuses to commit or push a merge conflict, checks its own thumbnails and lead images, and draws every code sample in one font. X_eTaL gained a cross-reference tool and a clippy-style linter, and settled on trying new language features as macros before any new syntax. And an X_eTaL program can now drive Blender, the start of 3D scenes, animation and rendering from an array language.
Fourth in the Array Languages series: X_eTaL-extensions, the third meaning of Extensible. Eleven small Rust libraries give X_eTaL programs what the interpreter should not reinvent: a database, sound, windows and 3D, a web server and HTTP, image files, fast linear algebra, a clock and hashing. Each sits behind a typed X_eTaL facade written one line per function by a macro, so a program never sees the plumbing. Here are the boundary, what it costs, and twelve demos, from a CO2 data notebook and a synthesizer to an earthquake report and a voxel world.
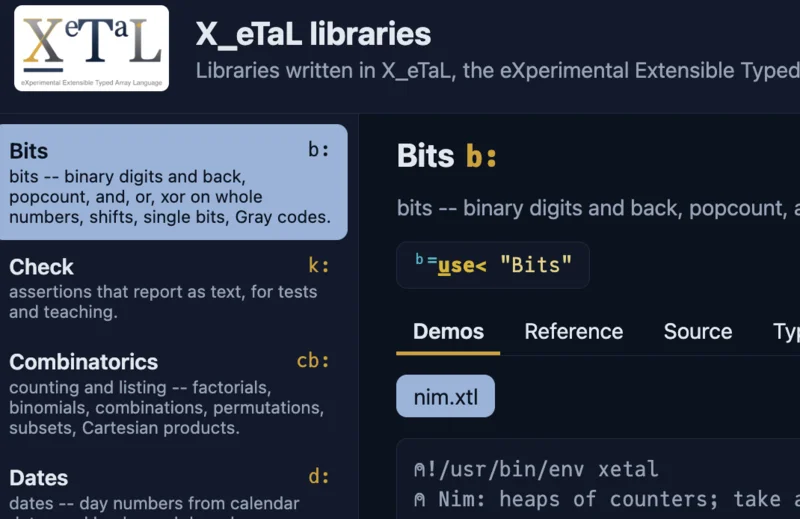
Third in the Array Languages series: X_eTaL-libraries, where the E in the name gets its first two meanings. Nineteen libraries, 168 functions, every one with tests, a live editable demo and a reference page in a cross-reference site searchable by type; six of them carry macros: date literals checked at compile time, math notation compiled, a graph whose node names become variables. The macros are source-to-source functions written in X_eTaL, type-checked after expansion, and placed here among Rust, Forth and APL's own execute.
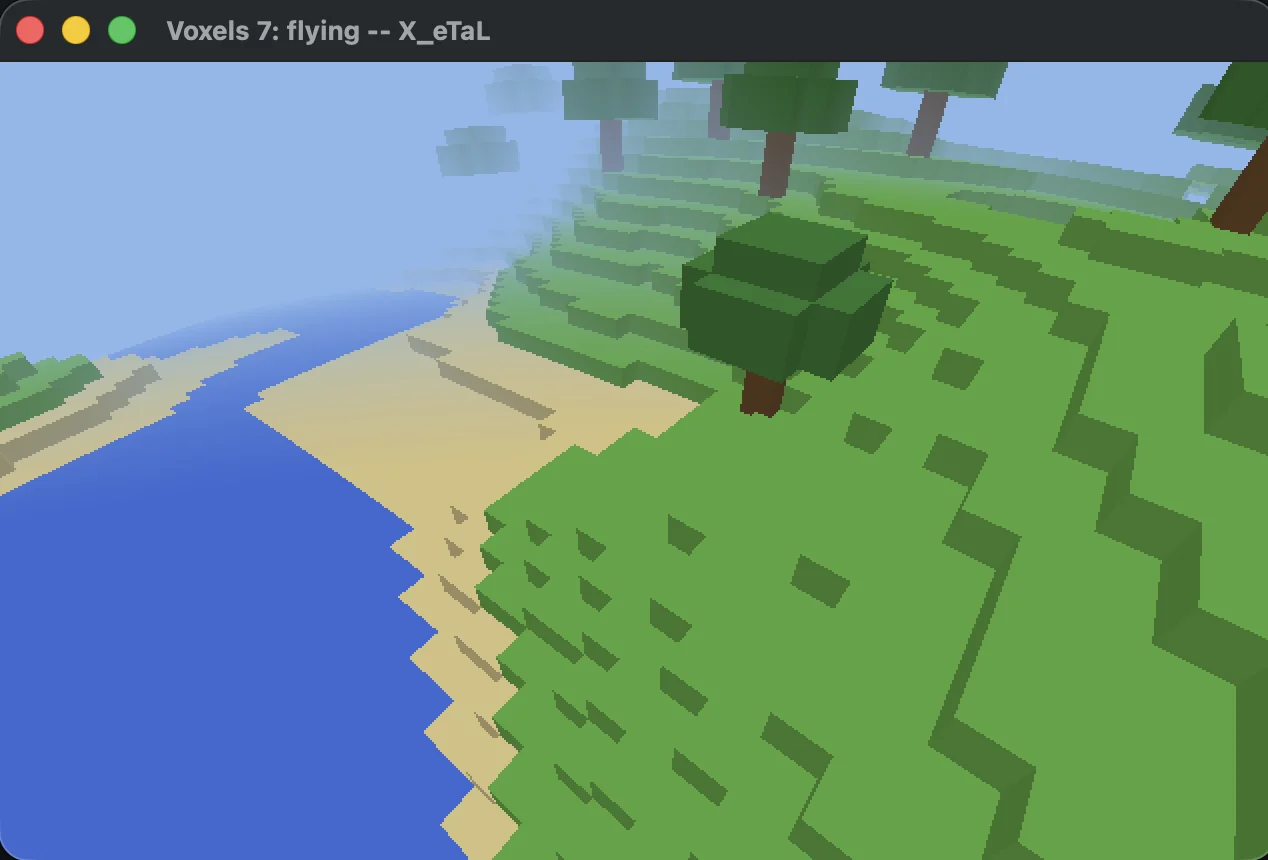
Kyle Croarkin wrote a voxel game in Dyalog APL on a bet with himself that APL's notation would make it easier. The heart of it is one line: a chunk of blocks is an array, and the faces worth drawing come from rotating that array six ways and comparing, the same move as the one-line Game of Life. This post follows the idea into X_eTaL, where a ladder of demos builds a world from one chunk to an endless landscape you can fly over, dig into, flood and light, with a game on top, drawn by a CPU rasterizer in Rust. By the way, the same voxels also draw a Rubik's cube.
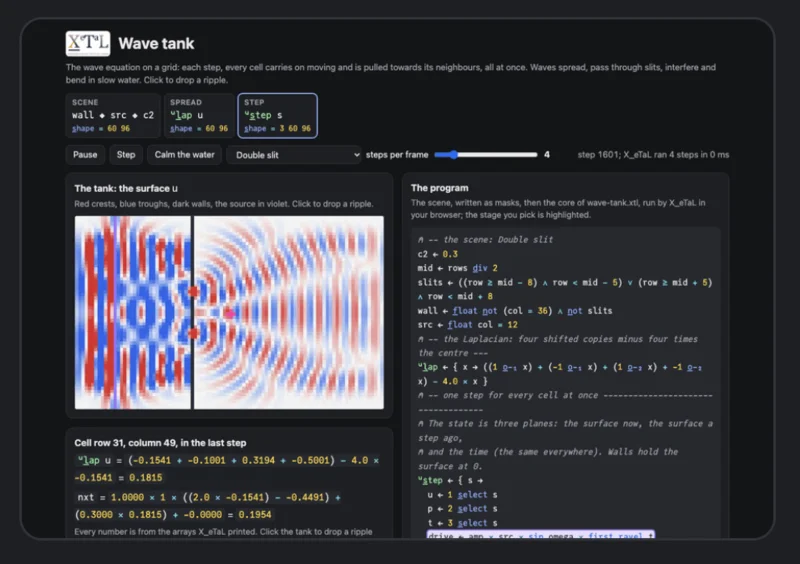
Second in the Array Languages series: X_eTaL-demos, small programs that produce something worth watching, each shown beside the array transformations that make it. Twelve are live in the browser, from the Life microscope to Fourier epicycles, and they tell one story: whole-array operations express spatial computation. One is built on a macro library of its own, one runs only at the command line as Unix pipe stages, and the Tower of Hanoi, from the language's classics, shows the same moves three ways.
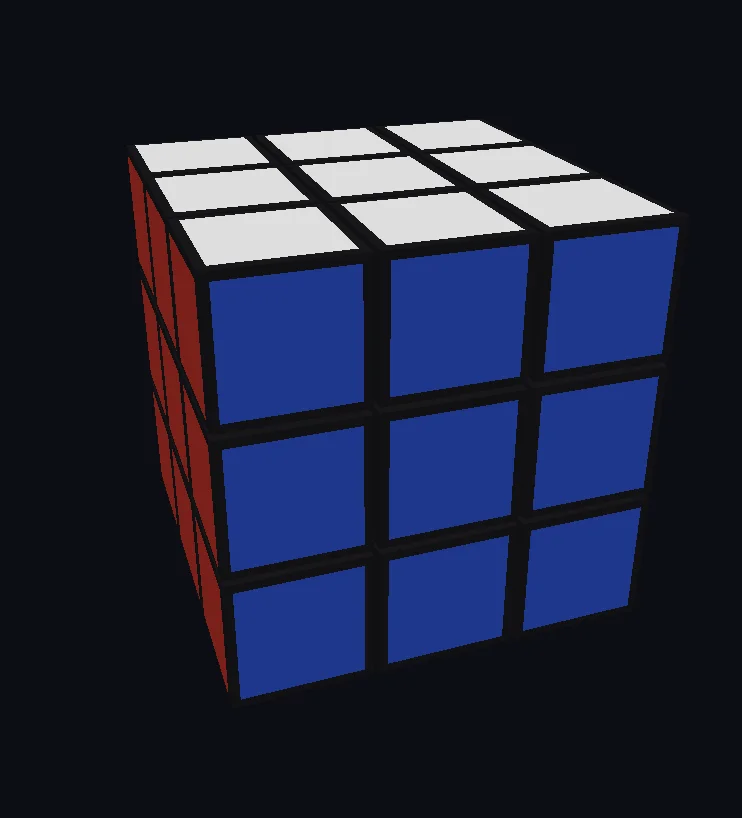
Steffen Smolka's Eigencube solves a Rubik's cube in under 400 lines of Python by treating it as linear algebra: each of 26 cubelets is an integer vector, its orientation a rotation matrix, and a turn one matrix product. This post follows the idea into two array languages: APLSV as it ran in 1975, through the sw-apl-workspaces library, and X_eTaL, where a whole batch of cubes is one array and every turn of every cube in a search is two matrix products.
X_eTaL, the eXperimental Extensible Typed Array Language, is an APL-family array language that differs from its ancestors on purpose: statically typed with Hindley-Milner inference, plain ASCII in with typography out, and extensible through libraries, macros and native code. First of a series, one post per repository: this one is the language itself --- the question it asks, how typography became the syntax, what it can do as of October 2026, and the programs inside the repo that prove it.
The first computer I built from a kit had 256 bytes of memory. The biggest machine on my bench today has 640 gigabytes. In between: core memory counted in words, a 4K static RAM card that cost nearly as much as the computer, the 640K wall and the memory that went around it, mainframes measured in megabytes, and a 1996 workstation with a gigabyte. Three charts --- how much, what it cost, how fast --- with the cost restated in 1977, 1985, 1995 and 2016 dollars; the past year, when memory prices went up fivefold for the first time in the series; a second table for the embedded boards, where memory still comes in four distinct sizes; and a question: should we be efficient with memory again?
To be a career software engineer, one skill is paramount: the ability to learn new things. Over many decades I have had to learn a new way to do something so many times that the list is the career. This Throwback Thursday draws it as timelines --- machines, operating systems, languages, editors, IDEs, version control, terminals, build tools, debuggers, documentation, collaboration and, lately, AI --- one bar per tool, mainframe to cloud, with a note on what each hand-over cost to learn.
This week's sharpening is mostly benches. Claude in the cloud recreated my development environment on a Linux host and now works the x86-64 side of MLOS while this Mac keeps the ARM side; a small Rust tool draws word clouds for future posts; the APL self-study course became a library the interpreter loads; a new ML language is under way, its notation still evolving and its name held back until there is a demo; the Docent matcher in sw-atlas is about to learn from the typed decision model; every GitHub landing page and social card got a pass; and I finally have a seat in #osdev and on OSDev.org. Ahead: two Zoom calls, and the benches they need --- sw-tos on a 32-bit MCU, APL on a small Linux board, and I2C and SPI device tests on COR24-TB and its emulator.
Made Visible #4: Rosetta M, a Stone with Four Faces
Sep 25, 2026
The first three things this series drew were memory maps. This one draws a notation that does not exist yet. Rosetta M is a mock-up of a proposed array language for machine learning, presented the way the Rosetta Stone presents a decree: the same thing in more than one script. Each of ten small computations is a stone whose faces are the mathematics as a paper writes it, one line of proposed notation, a live dataflow, and, where the computation trains, its loss trace --- with training time as the axis they all share, and every symbol on every face explained by its own callout. The CNN triple sum from ML #9 is the stone turned first.
TBT #12: The IBM 5100's APLSV --- (B) '75, Birds by Execute, and a Machine That Learns Tic-Tac-Toe
Sep 24, 2026
Last week was learning APL at a 2741; this week is using it professionally on the IBM 5100 --- the 1975 desk machine whose APL was APLSV with the time-sharing parts removed. That subtraction and its additions are the whole personality of sw-apl's (B) '75 mode: execute, quad system variables that are real variables, the quad system functions, a keyboard with a CMD key, and no I-beams. Two new workspaces show what the differences buy: BIRDS, the full Smullyan aviary reached through execute --- including the Sage, recursion without a name, in 1975 APL --- and TTTML, a machine that learns tic-tac-toe by playing itself, in about 15,000 bytes that would fit beside everything else in a 5110's 64 KB.
A reader searched this blog for the Y combinator and found nothing, which was accurate --- so here is the post. Smullyan's Sage bird is the Y combinator, Y f = f (Y f), but an eager evaluator diverges if you ever call it. sw-MLPL is strict, so the aviary builds the fixed point with a named partial instead: the applicative Sage, the Z combinator in bird costume. Here is the classical construction, why it diverges, how the APL lineage sidesteps the whole problem, why sw-MLPL should stay eager, and a three-step recipe for running a Sage today --- no language changes required.
There is a live demo on the lab bench: a typed decision model --- 33,065 parameters, about 250 KB with its weights, the whole page --- that reads a sentence and returns probabilities over a fixed set of replies, running entirely in the browser on sw-MLPL, with a trace of every decision behind every reply and a scrubbable timeline of its own training from random weights. Jev, TypeSafe's closed System One model, is the inspiration; the open-source response to it is wide; this is the lab's own entry, measured honestly --- including a probe of exactly why its replies sometimes miss. When the primitives prove viable, they land in sw-atlas, an index that knows the corpus, and in the campus tour guide. The facts live in the index. The model holds only the language.
TBT #11: APL\360 Revisited
Sep 17, 2026
APL\360 was the first APL you could actually type at --- IBM's 1968 implementation of Iverson's notation, used from a typewriter terminal with a special typeball. This is a look at what it did and did not do, why its ideas turned up in half the languages and libraries that followed, and a third APL of my own: sw-apl, a clean-room APL\360 in Rust that keeps the glyphs, the six-space prompt, the del editor, and the workspaces, and is checked against the printed examples in IBM's own manuals.
Coding agents are usually described from the outside: a product with a terminal UI, a permission system, a dozen tools, and a model behind it all. mlplcode is the inside, kept small: the whole control loop in sw-MLPL, an array language, with Rust only for the mechanisms the language cannot express and a local model for inference. One LLM primitive, six verbs, about 850 lines of MLPL that matter and 220 of Rust --- and a verifier standing between the model's claim of success and the real thing, because a 7B model will say it ran the tests when it did not.
The third system drawn by the same visualizer, and the one that breaks the pattern. MLOS is a Rust kernel whose scarce resource is not flash blocks or physical frames but resident model state --- weights, KV blocks, activations --- treated as kernel objects. Three systems now share one picture while meaning three different things by 'where is it in memory'.
A microscope for mixture-of-experts models, built in sw-MLPL: a tiny model --- 7,096 parameters today --- where every part, the router, the experts, the load-balance term, the expert cache, can be watched while it works, and swapped for a different implementation to compare. It exists for two reasons: to be the workbench for tiny models headed for the browser and for microprocessors with a few hundred megabytes and a fraction of a TOPS, and to put sw-MLPL under real load so its gaps turn into fixes. Its first real domain, a docent for the Software Wrighter Research Campus, produced a measured answer: a deterministic matcher beats the first trained docent, so the campus ships the matcher and the MoE docent stays research. The lessons step through their frames in a live demo.
Made Visible #2: MesaOS, the Conventional One
Sep 12, 2026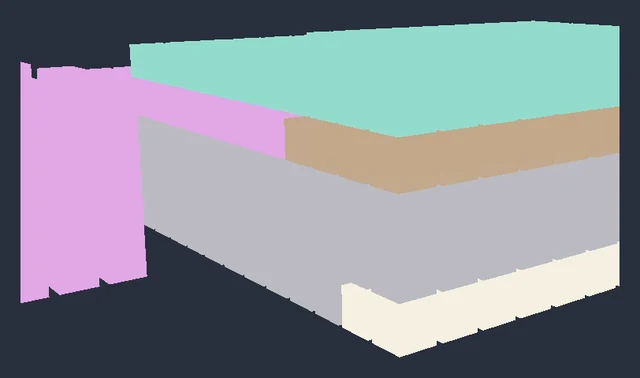
The second system drawn by the same memory visualizer, and the ordinary one: a 64-bit kernel with a physical frame allocator, virtual memory, a kernel heap and ELF programs in Ring 3. It has exactly the machinery the first system deliberately does without, which is what makes it a real test of whether one picture can serve both.
Personal Software #11: A Campus for the Public Work
Sep 12, 2026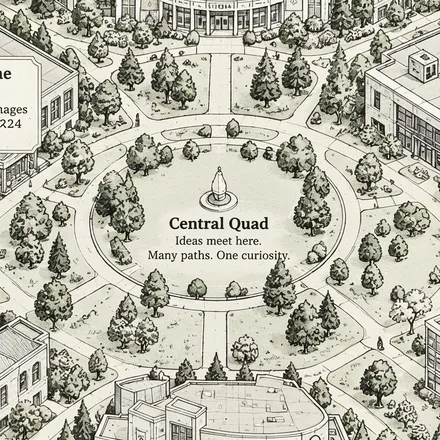
There are 133 public repositories spread across fifteen GitHub organizations, and no single place to stand and see them. This is the start of one: a 2.5D isometric campus where subjects are buildings, every place has a shareable address, and the organizing unit is a topic rather than a repository.
Made Visible #1: A Microkernel's Storage, Drawn
Sep 11, 2026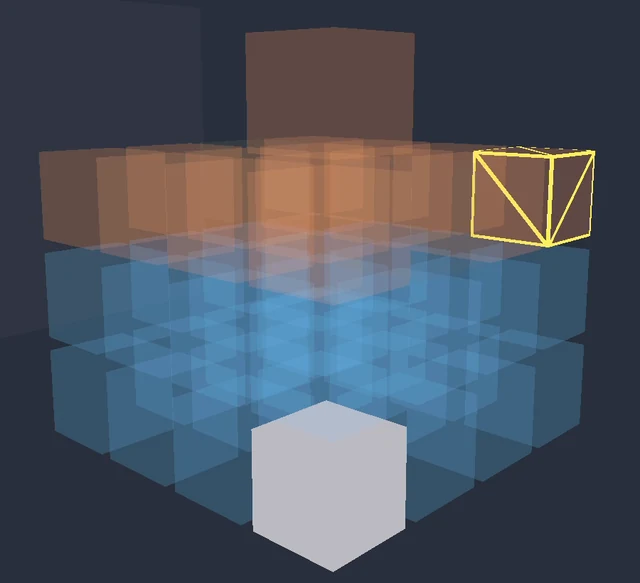
A memory map is one of the hardest things about an operating system to explain in prose, and one of the easiest to understand as a picture. This is an interactive 3D view of where a 24-bit microkernel on an FPGA soft CPU actually puts things --- and the three-layer split behind it, where the operating system knows nothing about graphics, the renderer knows nothing about operating systems, and an array language sits in the middle turning one into the other.

A CNN layer is defined with three nested summations. Saying that in an array language takes four pieces of vocabulary that sw-MLPL did not have: a sliding-window rearrangement, broadcasting a small kernel against a large stack of patches, reduction over several axes at once, and reduction by axis name. This is what each one lets you write --- and a fifth, differentiating through the window, that turns the result from a convolution you can compute into one you can train.
local-llm-loop is a Rust harness that drives opencode against a local model in a plan, execute, review loop: Rust deterministically owns the plan cursor and history while three separate LLM calls do the planning, the coding, and the verification. This is what has been measured so far across a fleet of machines spanning 12 GB to 64 GB --- which models clear the two hardware-independent gates, how long a complete loop takes on each box, and why tool-use reliability moves wall-clock more than raw tokens per second.
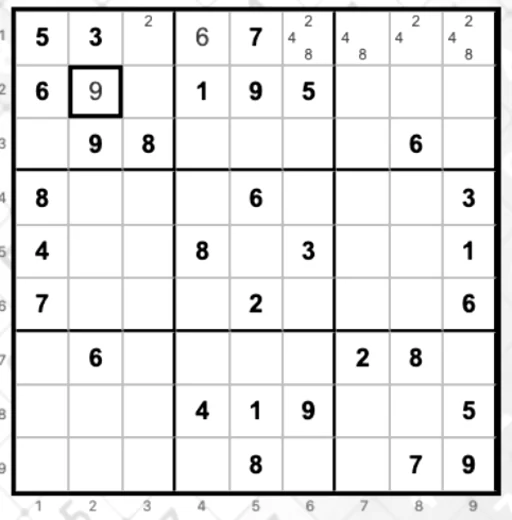
I was tired of ad-supported Sudoku apps, and I wanted to learn the more advanced solving strategies. So I vibe coded a browser Sudoku in Rust, Yew, and WASM --- first the game, then the part I actually wanted: a Learn mode that finds every strategy applicable to the live board and walks it step by step with animated highlighting, and a Show me mode that solves the board itself while explaining one technique at a time. A pencil-notes system followed from user feedback. The generator is seeded and fail-closed, and every puzzle it accepts has exactly one solution.
Status report on two bucket list items: developing operating systems, and building ML hardware. Three operating systems are in flight --- SWTOS, a preemptive microkernel running on a COR24 FPGA soft CPU and in the browser; a MesaOS fork used for Ring 3 experiments; and MLOS, a Rust kernel that virtualizes model state rather than memory pages. The hardware item is emufpga, a behavioral emulator for a Serial Parameter Machine that streams weights past the compute: 4 KiB resident instead of 269 MB on a 135M model, bit-exact, five clients served off one pass.
Saw #10: sw-MLPL General-Purpose Features, Libraries, Extensions, Graphics, and Networking
Sep 06, 2026
Four months of sw-MLPL work across fifteen repositories: 2,720 commits since June. The core language grew the general-purpose surface an array ML language normally lacks --- strings, records, sandboxed byte and filesystem I/O, JSON/TOML decoding, first-class function references, partial application, guaranteed-teardown error handling, and a compile-to-Rust path. Around it, thirteen companion repositories exercise that surface on mathematics, general programming, and ML tooling, and a native extension repository adds wgpu graphics, an HTTP client and server, and SQLite through a versioned C ABI.
Energy-based learning frames intelligence as making compatible configurations low energy and incompatible ones high energy. Hopfield networks made memory an energy landscape, Boltzmann machines made that landscape stochastic and learnable, and JEPA carries the idea forward into representation-space prediction.
nono is attractive because AI coding agents need real boundaries, but making nono, Pi, Ollama, and local models work together took iteration. The usable shape was not to wrap every layer. It was to sandbox Pi, let Pi call Ollama, and then find models that actually act instead of merely describing what they plan to do.
Pi is interesting because it does not try to become an IDE, platform, or operating system. After using it with a local Ollama model and one small package, the useful slant is simpler: a minimal agent loop uses the model's available context efficiently, and the lack of ceremony is the feature.
Three tools that turn out to be the same problem in disguise---Espanso for shared glyph input, Kate for one-XML-file syntax highlighting, and `gh gist create` standing in for ShareX---all earning their slot because they make collaborating on a new in-development language (PAL) cheap. Plus a deeper cut on the COR24 emulator: a three-layer I2C design (guest C apps / bit-banged bus state machine / pluggable device trait) that lets every COR24 language share the same I/O example library, with SPI sketched as a parallel phase 2.
In the 1980s, I worked at IBM on PL/X systems code for an MVS/ESA time-sharing service called AQ --- hundreds of developers editing source on green-screen 3270 terminals, submitting batch compile jobs, sometimes waiting an hour for results. Two colleagues built productivity tools that absolutely changed the workflow: PL/EDIT, a template-driven editor that expanded common PL/X forms via hotkeys long before IDEs or Emacs were common, and Mass Compile, a batch-queue scheduler that let you submit compile jobs for code you had not written yet. Both have just landed in my COR24 PL/SW live demo. This post tells the original story and shows what was rebuilt.
Three threads winding through the next chunk of the bucket list. First, source code in three dimensions: punch cards were 1D, screens are 2D, DiscoveryOne projects glyphs at (x, y, z) onto seven semantic facets. Second, five programming languages of my own currently in flight --- PL/SW, SWS, sw-MLPL, Tuplet, and DiscoveryOne --- each picking a different point on the build-axis / run-axis space. Third, the missing tool category that would tie all the language work together: educational visualizers that let you *watch* a compiler run --- step through a lexer, animate a parser, observe register allocation, see a heap fill and a garbage collector reclaim it, watch a JIT tier up. Most CS students never see any of this. They read about it. I want to build the surface that lets them watch.
Personal Software #9: Vibe-Maintenance --- When AI Agents Don't Just Write Code, They Fix Bugs
Apr 29, 2026
The corollary to vibe-coding is vibe-maintenance --- AI agents not just writing new code, but fixing bugs in the constellation of demos, compilers, interpreters, and runtimes that the lab has accumulated. Twenty-eight sw-embed repos closed 141 issues in eighteen days. The web-sw-cor24-demos Status tab visualizes that activity as a closed-issues heatmap and a commit heatmap, alongside repo-level Try-it / In-dev badges. The post walks through the four bug-fix patterns the activity reveals (capacity-limit bumps, subtle codegen bugs, surface-level language features rolling in, and cross-cutting tooling bugs), and the human skill the cadence does not eliminate: writing an issue title that names the symptom precisely enough for the agent to act on it.
Thirteen sw-embed repos --- BASIC, Forth, OCaml, Pascal, PL/SW, Smalltalk, Tuplet, Macrolisp, Snobol4, APL, plus the resident-shell trio of monitor/script/yocto-ed --- each invented their own way to load code, runtime, source, and data into the COR24 emulator. The first sw-launcher schema (v1.1) tried to canonize their layout with a fixed 8 x 128 KiB partition grid; the second (v1.2) threw the grid out and replaced it with named memory profiles plus a `heap_justification` block, because the survey's real finding was not that the layouts varied --- it was that several of them were leaking. Phase 1 is shipped: `sw-launch run echo` actually exits 0 and prints "A" through the captured UART of a real `cor24-run` process. The post walks through both schema revisions, the memory-stance reversal that drove v1.2, and what works end-to-end today.
First post in a new Dogfooding series. The Pascal p-code VM shipped with a bump allocator and a no-op free --- enough for small demos, intentionally not more. Then OCaml-in-Pascal (used to write the Tuplet lexer/parser) ran out of heap mid-parse, even after re-doubling the heap twice. YAGNI worked right up until I needed it. This post is about that crossing-over moment: what the bump allocator bought, what it cost, and what reclaim looks like when it finally has to ship.
sw-checklist is a personal-software Rust CLI I wrote to rein in AI coding agents: function/file/module/crate size limits enforced as warnings and failures. The post threads Brooks (essential vs accidental complexity) and Hickey (simple vs easy, complect vs decomplect) through that tool. The metrics are an accidental cost, but they pay rent --- AI agents that started out reacting to violations eventually anticipate them, and the long-run code stays focused on essential complexity. The metaphor for tech debt is a ratchet: clicks back are sometimes allowed, but the wrench only turns one way.
Tuplet is a new experimental PoC language with significant whitespace and glyphs, set up as a playground for future language experiments---and the reason for installing Espanso and configuring Emacs as a shared glyph-input layer (also useful for GNU APL). An integer/toy Smalltalk written in COR24 BASIC works as a forcing function for BASIC; Tuplet plays the same role for OCaml and Forth. A new browser-native Forth, proto-forth-wasm, runs via WASM. sw-MLPL splits into Linux/CUDA, Mac/MLX, and Web UI repos after its build dir crossed 35 GB. The COR24 emulator gains I2C support with examples, and the demo site's Status tab tracks the new languages with commits and issues.
After dictionary compaction turns one Forth source tree into different vertical profiles, the next rabbit trail goes horizontal: how does the same self-hosted Forth compiler target COR24, WASM, RV32I, or S/360 without forking the language, and how do forward references and mutually recursive words survive that split?
After optimizing FIND (rabbit-hole 2 and 3), the next move is to eliminate FIND entirely for deployment. This post walks the jump from dev image to runtime image: pruning shadowed redefinitions, dropping the compiler/REPL/instrumentation for production builds, and the pointer-rewriting work that actually makes compaction safe. Frames the whole thing as a Forth composer — one small core plus pluggable feature modules plus target profiles.
Brown et al. (2024) show that repeatedly sampling a small model --- and letting an automatic verifier pick the best candidate --- can beat single-shot frontier models at a fraction of the cost. DeepSeek-Coder-V2-Instruct jumps from 15.9% to 56% on SWE-bench Lite with 250 samples. Coverage scales log-linearly across four orders of magnitude. This post walks the paper, reproduces the shape of the result on an 8B vs 70B binary_search demo, and asks what changes when inference itself is the scaling axis.
Rabbit-hole #3: FORTH --- Life After Hashing
Apr 24, 2026
Phase 4 of the COR24 Forth ships without the XMX hash. What replaces it? A layered set of cheap optimizations --- numeric fast path, recent-hit cache, hot-token cache --- that target the interactive hot path without rebuilding the hash subsystem. Plus the instrumentation you need to know which words to actually cache.
Sagas assume linear plans. Daily use across parallel repos assumes surprises. The April AgentRail features --- insert/reorder/reopen, audit/snapshot, maintenance mode --- are what you only design after you actually live with the tool.
ML Frontier #05: Grokking --- Delayed Generalization
Apr 23, 2026
Train a small network past the point of zero training loss and sometimes --- thousands of steps later --- test accuracy suddenly jumps from random to near perfect. The model didn't just memorize; it discovered the rule. This is grokking, and the research explaining it reframes generalization as a phase transition.
A rabbit hole on FORTH, following the phase-4 direction set out in the self-hosting spectrum post. Dictionary lookup is the price Forth pays for readability: this post walks through what FIND does, how the all-asm kernel made it fast with a 2-round XMX hash and a 1-entry lookaside cache, and why phase 4 (forth-from-forth) is dropping the whole subsystem now that FIND lives in high-level Forth.
How much of a Forth kernel can be written in Forth instead of assembly? Four points along that spectrum, from a 3000-line all-asm kernel to a Forth-hosted cross-compiler that emits its own .s file. This post walks through phase 1 (all-asm), phase 2 (forth-in-forth, shipped with XMX-hashed FIND and a 1-entry lookaside cache), phase 3 (forth-on-forthish, first two subsets shipping — ,DOCOL plus Forth : and ;), and phase 4 (forth-from-forth, future). Plus the performance work — hashing, cache, adaptive web pump-loop, build-time snapshot.
Rust-to-Prolog solves the classic Lion and Unicorn logic puzzles---a reference implementation that sets up a self-hosting COR24 port: PL/SW for the WAM-style runtime, SNOBOL4 for the lexer and parser. All-Together-Now scales to many concurrent agents with mosh, tmux, and per-user isolation on Arch Linux. The COR24 assembler begins self-hosting. sw-MLPL advances in parallel.
Three BASIC games from three eras---UNIVAC 1108 Startrek whose Red Alert bell telegraphed Klingon encounters across the teletype room, a 1980s Trek text adventure typed in from a magazine listing on a TRS-80, and Robot Chase added at a friend's request---all running in the browser on an emulated COR24 integer BASIC implemented on a p-code VM written in Pascal.
All Together Now gained a multi-panel Web UI for coordinating Claude Code and opencode/GLM-5 agents. Fuzzit became an LLM-guided fuzzing tool that stress-tests CLIs and APIs. Vendoring in the COR24 compiler chain lets PL/SW and SNOBOL4 evolve independently. Emacs Graphics brings PaperBanana-styled SVG charts, menus, and presentations to Emacs buffers.
Saw #5: Sagas, Languages, and Compiler Chains
Apr 05, 2026
Agentrail-rs gained saga archiving for multi-saga projects. Meanwhile, a new ML language (MLPL) took shape, PL/SW got macros, and two compiler-chain fixes unblocked APL and BASIC on COR24.
Bucket List #2: A Landing Page for Software Tools
Apr 03, 2026
Two weeks of vibe-coding with agentrail-rs produced a landing page for the COR24 Software Tools ecosystem---a portfolio of bucket list items that are actually getting done: a Lisp with garbage collection, a p-code VM, two programming languages, a monitor, an editor, and more.
Two CLI tools got full Emacs packages this week---pjmai-rs for project navigation and reg-rs for regression testing. Meanwhile, a new multi-agent Program Manager called All Together Now went from zero to four phases: PTY orchestration, web dashboard, and wiki-based agent coordination.
Six wiki implementations in Rust, tracing thirty years of storage evolution from flat files to git commits. What started as a throwback project became infrastructure for multi-agent AI coordination---with a Compare-and-Swap API that lets multiple AI agents safely share state through wiki pages.
ML Frontier #04: Is Chain of Thought Real?
Mar 23, 2026
Chain of Thought prompting transformed AI reasoning in 2022. By 2026, the frontier has shifted from making CoT better to asking whether it reflects real reasoning at all---and when step-by-step thinking helps versus hurts.
agentrail-rs went from walking skeleton to ICRL core loop, dual memory, distillation, and a hybrid orchestrator---all in one weekend. Next up: domain-specific Layer 2 repos, tested against three new projects that require C, Rust, Lisp, and Web UI skills.
A Rust-based browser emulator for the COR24 instruction set architecture. Three tabs---Assembly, C, Rust---all running on the same COR24 CPU in your browser. Includes interactive tutorials, coding challenges, animated tours, self-test mode, realistic UART timing, and a complete ISA reference. No installation required.
Bucket List #1: Things I've Always Wanted to Build
Mar 21, 2026
A lifelong list of technical things I always wanted to learn and build---too busy during my career, too hard before AI. Now retired, I'm working through them for fun, no deadlines. This is the introduction to the list.
ML Frontier #03: Structure Beats Scale --- Knowledge Graphs and Domain-Specific Superintelligence
Mar 19, 2026
What if scaling AI didn't require bigger models---but better structure? Princeton research proposes Domain-Specific Superintelligence: smaller expert models grounded in Knowledge Graphs, where the graph itself serves as both curriculum and reward model for verifiable multi-hop reasoning.
reg-rs is a Rust CLI that captures command output as golden baselines and detects regressions on re-run. A clean-room rewrite of a tool I first used at Forte Software in 2000, later reimplemented as jregress at Sun (still maintained at Oracle), and now open-sourced in Rust with shell aliases, text-based test files, and AI-assisted test creation and maintenance.
XSkill gives multimodal agents persistent memory---Skills for structured workflows and Experiences for tactical lessons---improving tool use by 2-6 points across five benchmarks without retraining.
A no_std Rust driver for the BMP280 pressure sensor, extended to support dozens of sensors via I2C multiplexers for a patent proof-of-concept. The journey from single-sensor to multi-mux arrays, and the eventual upgrade to BMP581.
ML Frontier #02: In-Context Reinforcement Learning
Mar 16, 2026
Transformers can learn reinforcement learning policies from trajectory examples in the prompt---no weight updates, no gradient descent. ICRL turns agents from amnesiacs into learners by injecting successful execution traces into context.
Saw #2: reg-rs, avoid-compaction, and agentrail-rs
Mar 15, 2026
Three Rust CLI tools getting foundational upgrades: reg-rs moves to git-friendly text-based test definitions, avoid-compaction structures multi-session AI workflows with saga/step handoffs, and agentrail-rs adds in-context reinforcement learning to push agent reliability from 75% toward deterministic.
How to compile Rust for a CPU that rustc doesn't support---by targeting one it does. Uses MSP430 as a 16-bit stepping stone to generate code for the 24-bit COR24 RISC architecture, then traces the full pipeline from source to registers.
ML Frontier #01: Neural Collapse
Mar 09, 2026
Why do deep networks converge to elegant geometric structures? Neural collapse explains: during late training, class representations form a symmetric simplex structure. Research from 2024-2025 proves this is globally optimal in deep transformers and ResNets.
Saw #1: pjmai-rs, Rig, and langchain-rust
Mar 08, 2026
Sharpening the foundation: pjmai-rs gets critical Rust 2024 edition fixes and new features, plus a first look at Rig and langchain-rust---two Rust frameworks for building type-safe LLM agents and chain-based AI workflows.
pjmai-rs: Navigation History and Fuzzy Completion
Mar 07, 2026
New pjmai-rs features: navigation history to revisit recent projects, smarter fuzzy tab completion, subdirectory navigation, and improved stack management. Building on the TBT post with practical workflow enhancements.
rank-wav: Ranking Audio Files by Acoustic Quality
Mar 06, 2026
rank-wav is a Rust CLI that ranks WAV files by acoustic features like spectral centroid, bandwidth, and RMS energy. It computes 'pleasing' and 'best' scores to help you quickly triage audio samples, synthesis outputs, or sound design variants.
Five ML Concepts - #30: The Journey So Far
Mar 05, 2026
Episode 30 marks a milestone: 145 machine learning concepts covered across 30 episodes. From backpropagation to scaling laws, dropout to distribution shift, RAG to reward hacking. This retrospective celebrates the journey and announces what's next: Frontier ML Thinking—one concept, two minutes, deeper implications.
TBT #6: PJMAI-RS - A Shell That Knows Your Projects
Mar 05, 2026
PJMAI-RS is a Rust CLI tool that maintains a registry of your projects and lets you switch between them instantly with short aliases. The clever part: it uses exit codes to signal a shell wrapper, allowing a subprocess to change your working directory.
Five ML Concepts - #29
Mar 04, 2026
Five ML concepts in under 30 seconds each: Neural Collapse (late-stage geometric convergence of class representations), Grokking (sudden generalization after prolonged memorization), SAM (optimizing for flat loss regions under perturbations), Mechanistic Interpretability (analyzing internal circuits of neural networks), Self-Training Instability (feedback loops that amplify errors in self-generated data).
Five ML Concepts - #28
Mar 03, 2026
Five ML concepts in under 30 seconds each: Lottery Ticket Hypothesis (small winning subnetworks within large models), Sparse Activation (using only part of a model per input), Conditional Computation (dynamically routing inputs for efficiency), Inference Parallelism (distributing inference across devices), Compute Optimality (balancing model size, data, and compute).
Five ML Concepts - #27
Mar 02, 2026
Five ML concepts in under 30 seconds each: Elastic Weight Consolidation (protecting important parameters during new task learning), Replay Buffers (mixing past examples to prevent forgetting), Parameter Routing (activating task-specific parameter subsets), Memory-Augmented Networks (external memory modules for neural networks), Model Editing (targeted weight updates without full retraining).
A robust architecture: core model (rarely updated) + adapters (modular skills) + external memory (facts) + context manager (RLM-style) + logging and evaluation loop. Errors feed into memory first. Only recurring, validated improvements reach adapters.
Five ML Concepts - #26
Mar 01, 2026
Five ML concepts in under 30 seconds each: Data Augmentation (expanding training data with transformations), Caching Strategies (reducing latency by reusing computation), Constitutional AI (training models to follow explicit principles), Goodhart's Law (optimizing metrics distorts objectives), Manifold Hypothesis (data lies on lower-dimensional structures).
How AI Learns Part 6: Toward Continuous Learning
Mar 01, 2026
Continuous learning aims to absorb new information and skills over time without losing old capabilities. The key: learn often in memory, consolidate carefully in weights. Periodic consolidation, not constant updates.
Five ML Concepts - #25
Feb 28, 2026
Five ML concepts in under 30 seconds each: Label Smoothing (softening targets to reduce overconfidence), Miscalibration (confidence not matching accuracy), Representation Learning (automatically learning useful features), Adversarial Examples (inputs crafted to cause errors), Double Descent (test error decreasing twice with model size).
Large context windows are not a complete solution. As context grows, attention dilutes and instructions drift. Recursive Language Models treat context as a dynamic environment, rebuilding focus each step instead of dragging everything forward.
Lucy 20%: Upgrading My Home AI Cluster
Feb 28, 2026
Expanding my home AI cluster from 10% to 20% brain power with a new X99 motherboard and RTX 3090. Adding VoxCPM voice cloning, FLUX text-to-image, and Wan 2.2 text-to-video capabilities.
Continuing the music-pipe-rs story: a web demo with Bach and Baroque arrangements, the seq command for explicit note sequences, and GarageBand integration. Plus the generative music resources that inspired this project.
Five ML Concepts - #24
Feb 27, 2026
Five ML concepts in under 30 seconds each: Warmup (gradually increasing learning rate at start), Data Leakage (training on unavailable deployment info), Mode Collapse (limited generative output variety), Blue/Green Deployment (switching between parallel production environments), Reward Hacking (exploiting reward function flaws).
How AI Learns Part 4: Memory-Based Learning
Feb 27, 2026
Modern AI systems increasingly rely on external memory. RAG, CAG, and Engram-style modules shift 'learning' away from weights. The brain stays stable. The notebook grows.
Five ML Concepts - #23
Feb 26, 2026
Five ML concepts in under 30 seconds each: Emergent Behavior (capabilities appearing at scale), Tool Use (AI calling external tools), Loss Surface Sharpness (flatter minima generalize better), Learning Rate Schedules (adjusting learning rate during training), Canary Deployment (gradually rolling out new models safely).
How AI Learns Part 3: Weight-Based Learning
Feb 26, 2026
Weight-based learning modifies the neural network itself. Pretraining, fine-tuning, LoRA, alignment methods, distillation---each changes the brain permanently. Slow to change, but forms the stable core.
A browser-based IBM 1130 system emulator with authentic console panel indicator lights, keypunch, printer, and assembly game. Experience the full 1965 minicomputer ecosystem through interactive simulations. Work in progress.
Five ML Concepts - #22
Feb 25, 2026
Five ML concepts in under 30 seconds each: RSFT (rejection sampling fine-tuning with filtered outputs), Model Steerability (adjusting behavior at inference time), LSTM (long short-term memory for sequences), Why More Data Beats Better Models (data scale trumps architecture tweaks), System Reliability vs Model Quality (balancing accuracy with uptime).
Two fundamentally different failure modes plague AI systems. Catastrophic forgetting destroys old knowledge when learning new skills. Context rot loses early instructions in long conversations. Different problems, different solutions.
Many-Eyes Learning: Intrinsic Rewards and Diversity
Feb 24, 2026
Expanding many-eyes learning with intrinsic rewards and a new web visualization. CuriousScout uses count-based novelty, OptimisticScout uses optimistic initialization. The key trade-off: diversity helps during exploration, but once Q-values converge, all scouts should follow the same optimal policy. Strategy quality matters more than diversity in simple environments.
How AI Learns Part 1: The Many Meanings of Learning
Feb 24, 2026
When people say 'AI learned something,' they usually mean one of four very different things. Understanding these time scales---from milliseconds to years---is essential for building AI systems that improve safely over time.
Five ML Concepts - #21
Feb 24, 2026
Five ML concepts in under 30 seconds each: Prompt Injection (malicious instructions overriding AI behavior), Jailbreaks (bypassing safety constraints), GRU (gated recurrent units for sequences), Planning vs Prediction (action evaluation vs forecasting), Production Rollbacks (reverting to stable model versions).
music-pipe-rs: Unix Pipelines for MIDI Composition
Feb 24, 2026
Personal Software continues. music-pipe-rs takes the Unix philosophy to MIDI composition---small tools connected by pipes. Start with a seed, generate motifs, transform, visualize, convert to MIDI. Deterministic output from a single seed at the pipeline head.
midi-cli-rs: Extending with Custom Mood Packs
Feb 23, 2026
Personal Software grows. midi-cli-rs now supports custom mood packs---TOML files that extend built-in moods with your own musical variations. No Rust required. Define tempo, key, intensity, and let the generators handle the rest.
Five ML Concepts - #20
Feb 23, 2026
Five ML concepts in under 30 seconds each: VAEs (generative with structured latents), Uncertainty Estimation (know when you don't know), Interpretability (distributed representations resist explanation), Gradient Noise (mini-batch variation), Human-in-the-Loop (human oversight for critical decisions).
Five ML Concepts - #19
Feb 22, 2026
Five ML concepts in under 30 seconds each: Autoencoders (compress and reconstruct), Correlation vs Causation (co-occurrence isn't cause), Curriculum Learning (easy to hard), Failure Analysis (categorize errors), Covariate Shift (new inputs, same task).
ICL evolved from emergent surprise (2020) to mechanistic understanding (2022) to engineered capability (2026). Transformers implement implicit gradient descent during inference---they learn without weight updates. The frontier: models learning from their own feedback. Not magic. Meta-learning in plain sight.
JSON is everywhere, but it's not the only option. This post explores data formats beyond basic JSON—JSONL for streaming, JSONB for fast queries, Protocol Buffers for compact wire formats, YAML/TOML for human editing, and TOON for LLM efficiency. Each has trade-offs: pick two of readability, compactness, or speed.
Five ML Concepts - #18
Feb 21, 2026
Five ML concepts in under 30 seconds each: Preference Learning (train from comparisons), Ensembling (combine models for robustness), ML Fragility (breaks on distribution shift), Epoch (one pass through data), Cost vs Quality (bigger isn't always better).
Five ML Concepts - #17
Feb 20, 2026
Five ML concepts in under 30 seconds each: Benchmark Leakage (test data contamination), Concept vs Data Drift (changed relationships vs inputs), Weight Decay (L2 penalty for simplicity), Scaling Laws (predictable performance growth), Shadow Deployment (test alongside production).
midi-cli-rs: Music Generation for AI Coding Agents
Feb 20, 2026
Personal Software via Vibe Coding: a music tool for AI agents. midi-cli-rs provides mood presets (suspense, upbeat, calm, jazz) so agents can generate complete audio compositions from simple commands. No music theory required.
Five ML Concepts - #16
Feb 19, 2026
Five ML concepts in under 30 seconds each: Train/Val/Test Split (separate data roles), Overconfidence (high probability wrong predictions), Batch Normalization (stable training), Optimization vs Generalization (low train loss doesn't mean good test), A/B Testing (compare with experiments).
TBT #4: ToonTalk - Teaching Robots to Program
Feb 19, 2026
ToonTalk is a 1995 visual programming environment where you train robots by showing them what to do. I vibe coded tt-rs, a Rust/WebAssembly reimplementation with boxes, scales, birds, nests, and robots---programming by demonstration for the browser.
Multi-Hop Reasoning (2/2): The Distribution Trap
Feb 18, 2026
RSFT on easy examples made performance worse---27% vs 37% SFT baseline. Training distribution must match evaluation distribution. Easy examples teach shortcuts that fail on hard problems. The fix is one flag change.
Part 2 of implementing the Share algorithm: after fixing critical bugs (zero-gradient saddle point, half-parameter training), routing-based coefficient selection achieves zero regressions. Result handling improved 40% to 50%. We're 60% through verifying the paper's claims.
Five ML Concepts - #15
Feb 18, 2026
Five ML concepts in under 30 seconds each: Perplexity (how surprised by data), Catastrophic Forgetting (new learning erases old), Weight Initialization (starting values matter), Curse of Dimensionality (high-D makes data sparse), Monitoring (track performance and drift).
Five ML Concepts - #14
Feb 17, 2026
Five ML concepts in under 30 seconds each: ROC/AUC (performance across thresholds), Spurious Correlations (coincidental patterns), Gradient Clipping (limit gradients for stability), Loss Landscapes (error surface over parameters), Cold Start (no history for new users).
Five ML Concepts - #13
Feb 16, 2026
Five ML concepts in under 30 seconds each: Calibration (predicted probabilities match outcomes), Shortcut Learning (exploiting spurious patterns), Early Stopping (halt when validation plateaus), Universal Approximation (NNs can fit any function), Checkpointing (save model state).
Five ML Concepts - #12
Feb 15, 2026
Five ML concepts in under 30 seconds each: Precision vs Recall (correct positives vs finding all), OOD Inputs (data unlike training), Batch Size (examples per update), Inductive Bias (built-in assumptions), Latency vs Throughput (speed vs capacity).
Personal Software for education: a neural network platform where every step is visible---no framework magic. CLI with progress bars, web UI with real-time loss charts, WASM for browser execution. Built via Vibe Coding to watch XOR training reveal why hidden layers matter.
Cat Finder: Personal Software via Vibe Coding
Feb 14, 2026
Personal Software via Vibe Coding: I needed to find cat photos scattered across my system. Instead of cloud services or app stores, I described what I wanted to Claude Code and got a working Rust CLI tool using YOLOv8 and ONNX Runtime. Privacy-first, locally-run, and mine to modify.
Five ML Concepts - #11
Feb 14, 2026
Five ML concepts in under 30 seconds each: RNN (sequential processing with memory), Chain of Thought (step-by-step reasoning), Softmax (scores to probabilities), MoE (route inputs to specialists), Distribution Shift (training vs deployment mismatch).
RLM: Recursive Language Models for Massive Context
Feb 13, 2026
When data won't fit in a context window, RLM expands the workspace instead. The MIT paper achieves 87-91% accuracy where standard prompting scores 0%. My Rust implementation provides four capability levels from DSL commands to WASM sandboxing to LLM delegation.
Five ML Concepts - #10
Feb 13, 2026
Five ML concepts in under 30 seconds each: CNN (sliding filters for image features), Encoder-Decoder (compress then generate), RAG (retrieve context before generating), Few-shot Learning (learn from prompt examples), Distillation (small student mimics large teacher).
TBT #3: Vector Graphics Games
Feb 12, 2026
Before pixels, there were vectors. Vibe Coding classic arcade games (Asteroids, BattleZone, Tempest) in Rust/WebAssembly with wgpu rendering---from my first encounter with an IBM 2250 to playable browser demos, all built in one day with Claude Code.
DyTopo: Dynamic Topology for Multi-Agent AI
Feb 12, 2026
When multiple AI agents work together, fixed communication patterns fail at scale. DyTopo rebuilds the graph each round based on semantic similarity between what agents need and what they can offer, preventing context explosion while enabling adaptive collaboration.
What happens when you fine-tune a model on new tasks? It forgets old ones. This post documents our implementation of the Share algorithm in Rust—using SVD-based subspace extraction to enable continual learning without catastrophic forgetting. Part 1 covers the problem and initial negative results.
Five ML Concepts - #9
Feb 12, 2026
Five ML concepts in under 30 seconds each: Dropout (random disabling prevents overfitting), RLHF (learn from human preferences), Inference (using trained models), Quantization (lower precision for efficiency), Flash Attention (block-wise for memory savings).
From behavioral emulation to real implementation: integrating hash-based Engram memory with HuggingFace models. The gating mechanism is critical---it learns when to trust memory lookup and when hash collisions would add noise. Engram excels at exact-match retrieval, not generalization.
Five ML Concepts - #8
Feb 11, 2026
Five ML concepts in under 30 seconds each: Bias-Variance Tradeoff (balance under/overfitting), Diffusion (generate by learning to denoise), KV Cache (store past keys/values), Mixed Precision (lower precision for speed), MLA (compress attention into latent space).
Five ML Concepts - #7
Feb 10, 2026
Five ML concepts in under 30 seconds each: Cross-Validation (rotate held-out data), GPT (predict next token at scale), GQA (shared keys/values for efficiency), Context Window (how much the model sees), Self-Attention (each token attends to all others).
Five ML Concepts - #6
Feb 09, 2026
Five ML concepts in under 30 seconds each: Regularization (constraints to prevent overfitting), BERT (bidirectional masked language modeling), RoPE (position via rotation in attention), Prompting (craft inputs to steer outputs), Positional Encoding (tell model where tokens are).
Five ML Concepts - #5
Feb 08, 2026
Five ML concepts in under 30 seconds each: Perceptron (single linear unit ancestor), Pre-training (learn general patterns first), Speculative Decoding (draft fast, verify in parallel), In-Context Learning (adapt from prompt examples), Latent Space (internal representations where similar things cluster).
Five ML Concepts - #4
Feb 07, 2026
Five ML concepts in under 30 seconds each: Activation Functions (introduce nonlinearity), Transfer Learning (reuse knowledge across tasks), VLM (joint image-text understanding), Adam (adaptive learning rates), Superposition (many concepts in overlapping representations).
Five ML Concepts - #3
Feb 06, 2026
Five ML concepts in under 30 seconds each: Loss Function (how far off predictions are), Overfitting (memorizing vs learning), Fine-tuning (specializing pre-trained models), LoRA (efficient adaptation with small matrices), Tokenization (breaking text into digestible pieces).
TBT #2: Pipelines on OS/390
Feb 05, 2026
Unix invented pipes. Mainframes reinvented them for records, not bytes. This Throwback Thursday recreates CMS/TSO Pipelines in Rust with a visual debugger, demonstrating record-oriented dataflow from the 1996 Olympics web server era.
Small Models (6/6): Which Small AI Fits YOUR Laptop?
Feb 05, 2026
Which small AI fits your laptop? Benchmarking Phi-2, Gemma-2B, and SmolLM on the 2-3B efficient frontier. Phi-2 achieves 61.7% MMLU with only 2.7B parameters, beating models 5x larger through synthetic textbook training. Data quality beats parameters.
Five ML Concepts - #2
Feb 05, 2026
Five ML concepts in under 30 seconds each: Gradient Descent (walk downhill to minimize error), Attention (focus on what matters), DPO (align from preference pairs), Learning Rate (step size tradeoff), Temperature (dial between predictable and creative).
Small Models (5/6): Max AI Per Watt
Feb 04, 2026
One billion parameters: the sweet spot for AI. Big enough to reason, small enough to run anywhere. Comparing TinyLlama, Llama-3.2-1B, StableLM, and Pythia with LoRA fine-tuning in minutes and speculative decoding for 2-3x speedups.
Five ML Concepts - #1
Feb 04, 2026
Five ML concepts in under 30 seconds each: Backpropagation (learning by flowing error backward), Transformers (attention over all tokens), Mamba (linear-time sequence modeling), Hallucination (confident nonsense), and Embeddings (meaning as coordinates).
Solving Sparse Rewards with Many Eyes
Feb 03, 2026
Single explorer: 0% success. Five explorers: 60% success. Sparse rewards are an information problem, not a compute problem. Using multiple scouts with different exploration strategies, we gather diverse discoveries that benefit a shared learner.
Small Models (4/6): This AI Has a Visible Brain
Feb 03, 2026
LLMs are black boxes. Baby Dragon Hatchling uses brain-inspired sparse coding with 80% sparsity, making only 20% of neurons active per token. When fewer neurons fire, each one carries interpretable meaning. Train it on Shakespeare and actually see what's happening inside.
MCP: Teaching Claude to Play (and Trash Talk)
Feb 02, 2026
Teaching Claude to play tic-tac-toe and trash talk using Model Context Protocol (MCP). A Rust server exposes 6 tools via JSON-RPC over stdio, proving MCP standardizes AI tool integration across any compatible language model.
Small Models (3/6): Planner + Doer = Genius
Feb 02, 2026
27 million parameters beats o3-mini on ARC. The Hierarchical Reasoning Model separates planning from execution, mimicking the brain's dual-process theory. It achieves 40% on the hardest reasoning benchmark where most LLMs score under 5%.
Implementing Deepseek's Engram paper on conditional memory. Instead of recomputing common patterns through O(n^2) attention, Engram provides O(1) lookup for cached results. Our LoRA-based behavioral approximation achieves 58% loss reduction in 10 seconds.
A 135M parameter model goes from 0% to 75% accuracy in 5 minutes. Using knowledge graph-guided training with rejection sampling, we teach multi-hop reasoning with scaffolding during training, then remove it at inference.
Small Models (2/6): AI in Your Pocket
Feb 01, 2026
AI in your pocket, no internet required. Pocket Eliza++ runs MobileLLM-350M on Android via llama.cpp and JNI, creating a privacy-first therapist chatbot. The 260MB quantized model achieves ~10 tokens/second on mid-range phones.
Implementing Deepseek's mHC (Manifold-Constrained Hyper-Connections) paper. Using Sinkhorn-Knopp iteration to create doubly-stochastic matrices, mHC maintains training stability at 48 layers where standard hyper-connections explode. Cross-platform validation on Apple Silicon and NVIDIA.
Small Models (1/6): 976 Parameters Beat Billions
Jan 31, 2026
The best LLMs score zero on hard mazes. A model with 976 parameters scores 85%. The Tiny Recursive Model uses think-act cycles with deep supervision, proving iteration beats scale for tasks requiring backtracking and spatial reasoning.
Welcome to Software Wrighter Lab
Jan 30, 2026
Introduction to Software Wrighter Lab: a blog, YouTube channel, and GitHub repos exploring AI coding agents, systems programming in Rust, and practical ML implementations. Written by Mike Wright, a software engineer with 40+ years of experience from mainframes to modern AI.
TBT #1: My First Program Was a Horse Race
Jan 29, 2026
My first program was a horse race game in APL on an IBM mainframe in 1972. This Throwback Thursday post recreates it using GNU APL, exploring array-oriented programming and the ideas that shaped languages from J to NumPy.